
 Posts


Introduction:
We discussed about dependency parsing in part 2 of spacy exploration series. Now, in the part 3 of our spacy exploration, we will explore some more concepts of NLP usages by spacy pipelines and utilities. Let's dive in.
How does spacy work internally?
Spacy uses all types of optimizations possible to make the processing as fast as possible. One of the main trick in doing so is to use hash code for the strings, and turn them into string as late as possible. The way it helps is that, digits take fixed spaces and can be processed faster than them in most of the operation. For this reason,
all strings are hash coded and the vocabulary object behaves like a double dictionary, in which using the hash you can find the string, and using the string, you can find the hash. See the following examples to get the idea about hashing:

Now, let's go over the data structures of the main objects in nlp. First we will see how to create a doc object manually to understand the real structure of a doc object. For creating a doc object, we can use the Doc object. Let's see how to create a doc object manually in the next example:

See how nlp.vocab is entered in place of vocab and the word and spaces list is provided to structure the doc. Internally spacy also works like this too.
Next, we will see how the Span objects work internally. For creating a span, we provide start and end parameters to the doc object. To manually create we will do the same, but we will directly use the span object to create the Spans manually. Let's see the code snippet to check how it is done.

Next, let's look into the spacy pipelines. We have already seen how processing a doc using nlp(doc) creates all the entities and dependency tags, but we need to understand how internally the nlp pipelines are built so that this works.
In the nlp pipeline, one by one, a text goes through tokenizer, tagger, parser and ner; and embeds the results in the doc. In such a pipeline, first the text is tokenized using tokenizer, and then the doc object stores the tokens as doc elements. After this, once the pos tagger runs on doc, the parts of speech are tagged and the token.pos tags are filled. After this, once the dependency parser is run, the dependency related params are filled and generated. Finally, ner element in the pipeline detects the entities and stores them in the doc.ents i.e. entities list.

In short, this is how a nlp pipeline performs all the operations on a text piece using the pipeline. When we load a model, the meta.json file of this model contains this pipeline structure too. Thus when the model is called, the model uses this pipeline info from the meta file and creates the actual pipeline.
Now, finally, the question is that, how to know what are the pipeline elements and can we know them from program? the answer is yes; we can.
Using pipe_names attribute, one can get the list of elements in the nlp pipelines. as well as using pipeline attribute one can get the list of the pipeline objects in the pipeline.

Also, to disable any pipe element one can use the disable parameter of the nlp object. i.e.let's say you have ['tagger','parser','ner'] in the pipeline and you write nlp.disable_pipe("tagger"); then the parser will not perform in the pipeline.
So in this part, we have explored the structures and pipelines of spacy. In the next part, we will explore how to create custom pipeline elements and handle them in spacy.
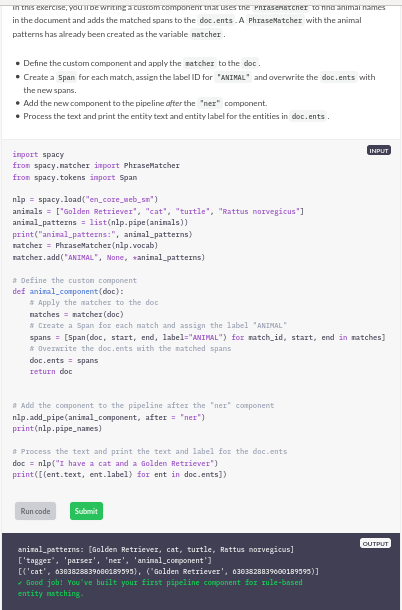
First let's learn to write custom pipelines. There are many reasons to add custom pipelines. One of the many is to add custom functions or custom entities. According to spacy these are the reasons for creating custom pipelines:


You can easily see, there are two types of parameters, i.e. last and first, and, before and after. Last and first is used to append the custom components in the end and the beginning of the nlp pipeline. The before and after parameter is used to append the custom components in the pipeline before or after some pipeline element. Let's see some examples of creating and appending such custom components.

In this example, clearly the custom_component, to count doc length in tokens is added in the first of the pipeline. Let's see some more examples about creating custom component:

Comments
Post a Comment